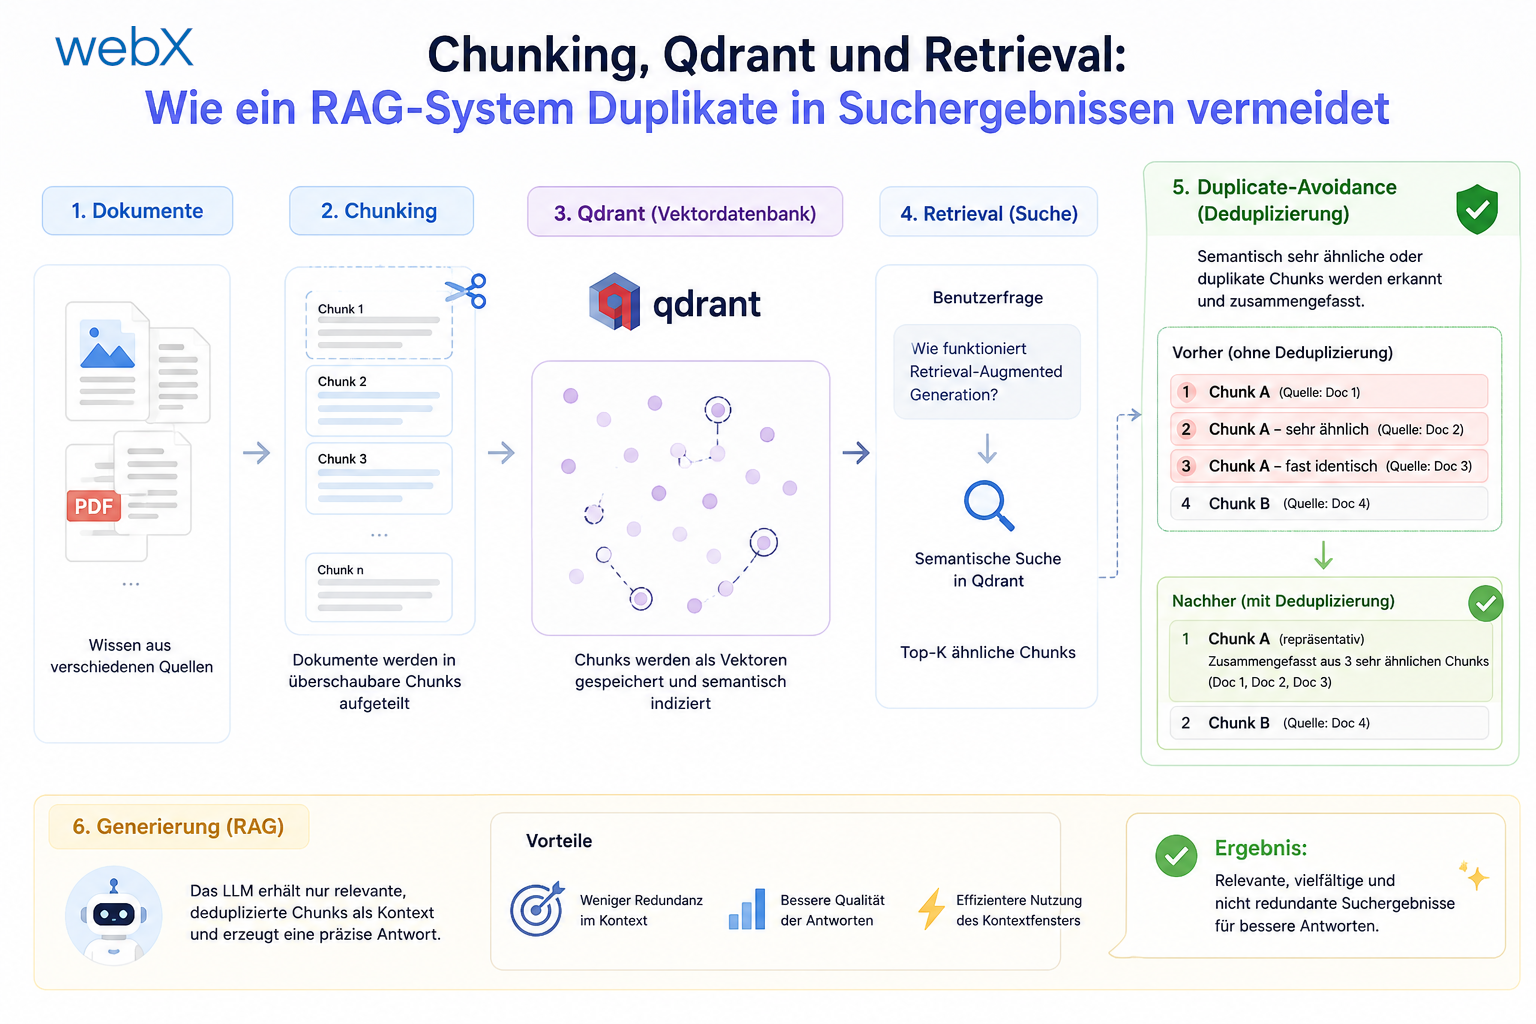
Chunking, Qdrant and retrieval without duplicate RAG search results
I check the new path from worker to search so that a long capture is not only processed, but also appears cleanly as one result.

I check the new path from worker to search so that a long capture is not only processed, but also appears cleanly as one result.
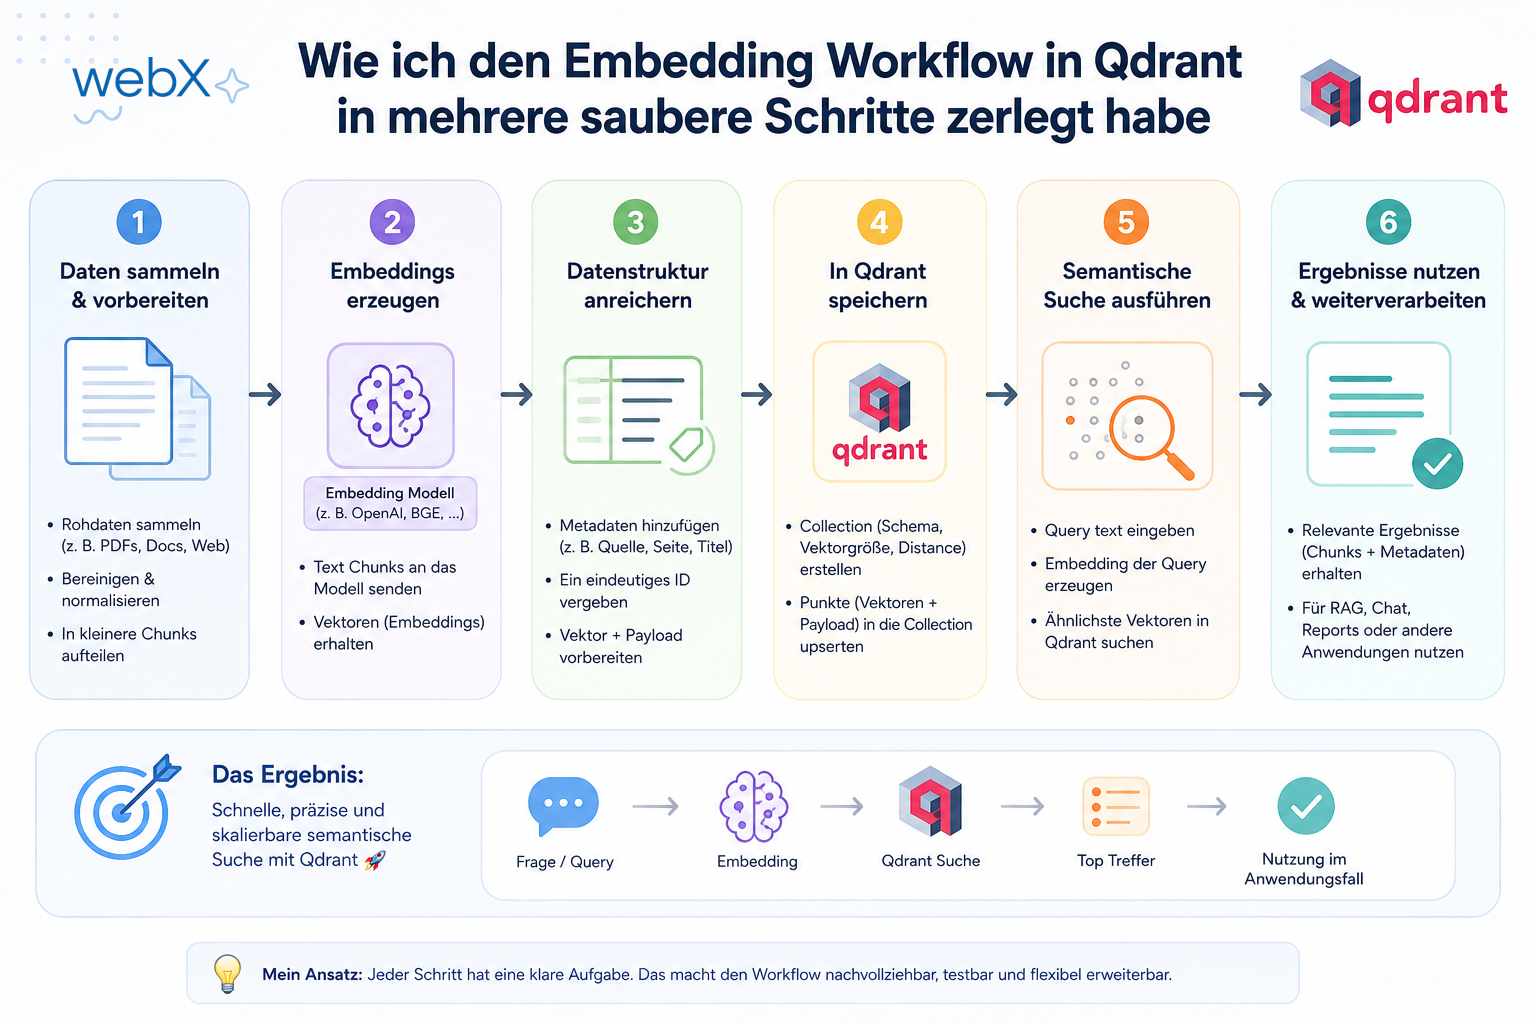
I rebuilt the worker so that one capture produces multiple token chunks, each chunk is embedded individually, and storage in Qdrant remains completely isolated.
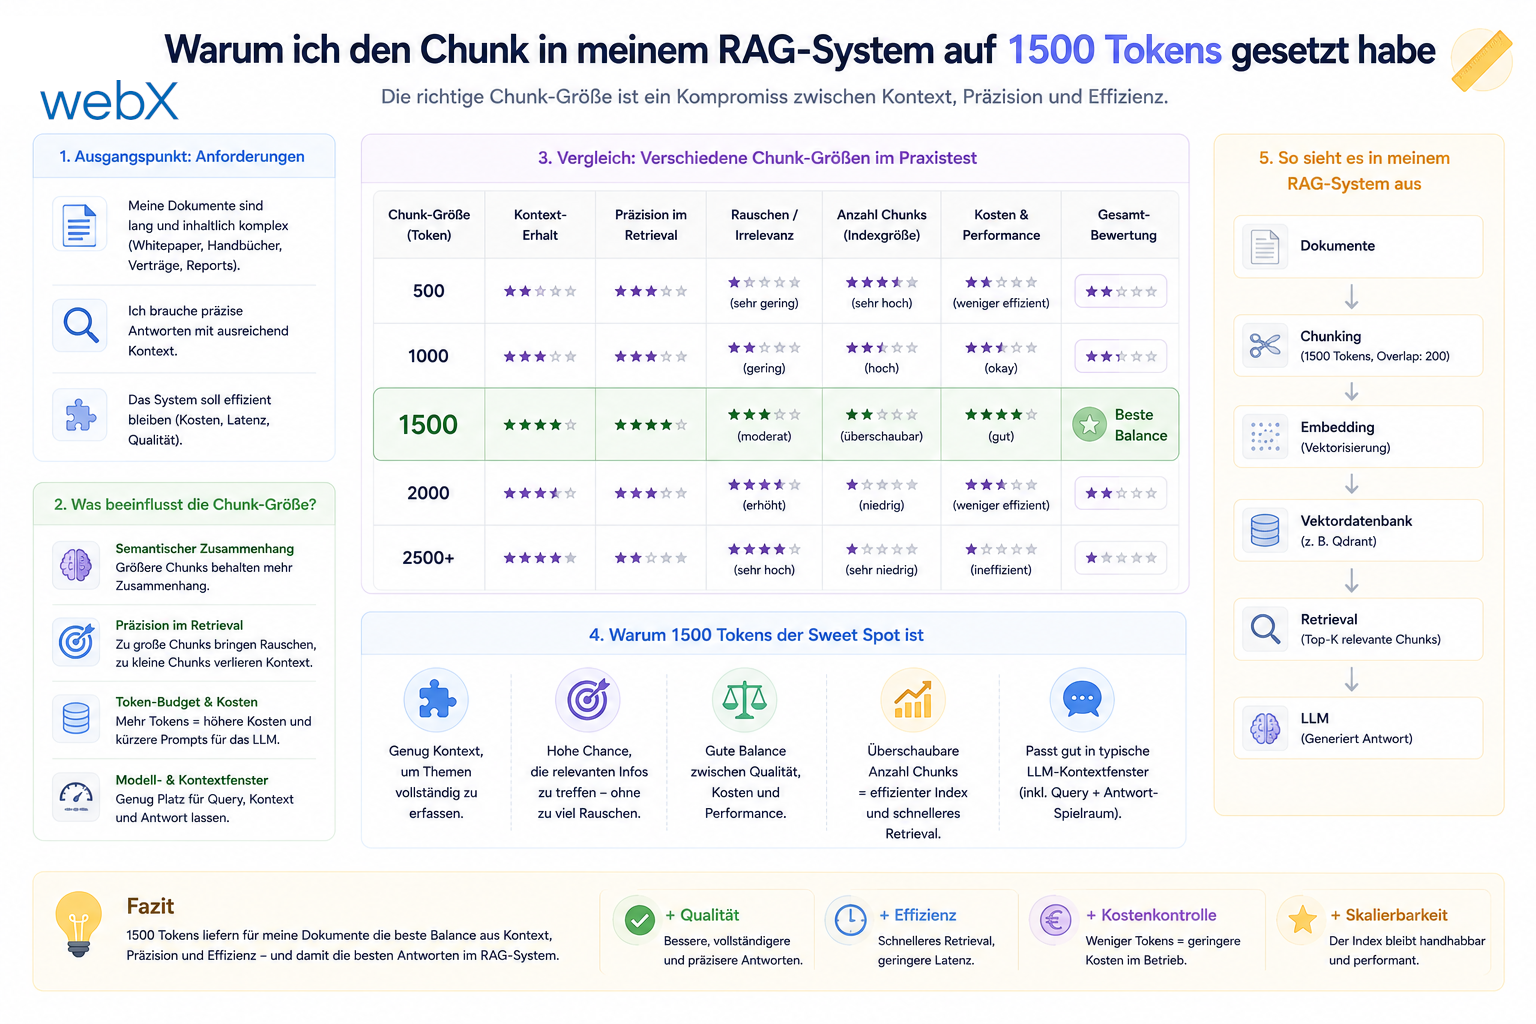
The migration to bge-m3 brought an 8192-token limit. Nevertheless, I deliberately set the chunk limit to 1500 tokens to preserve semantic focus.
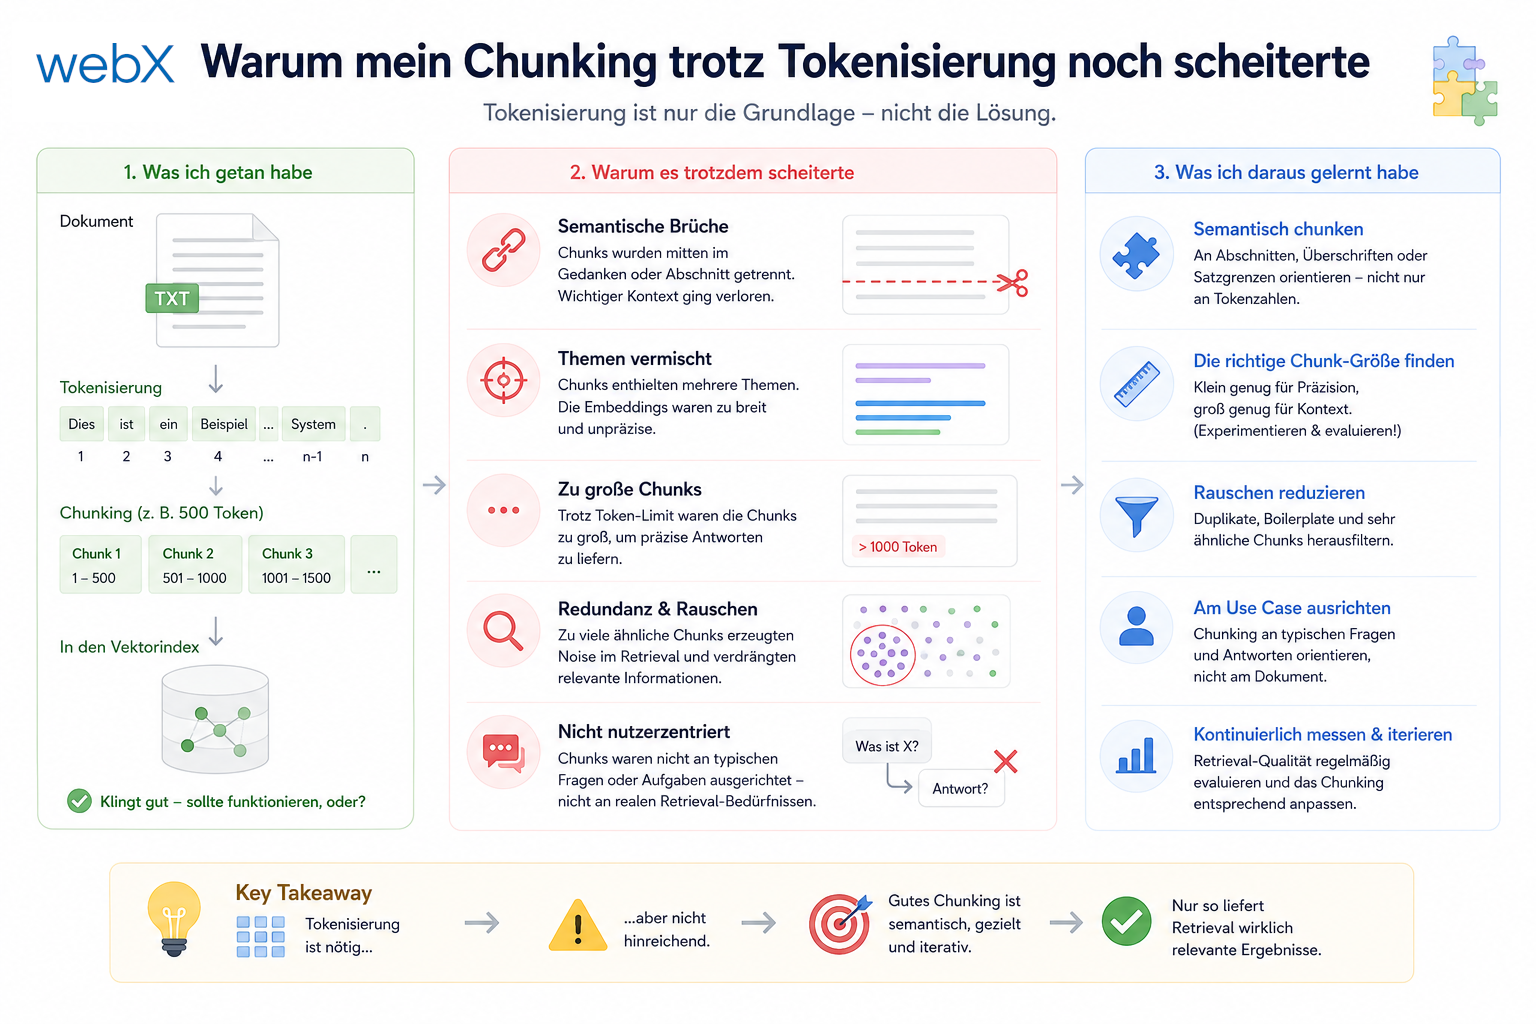
I had already implemented text splitting, but the context error kept appearing. Only when I accounted for the token budget and special tokens did the cause become clear.
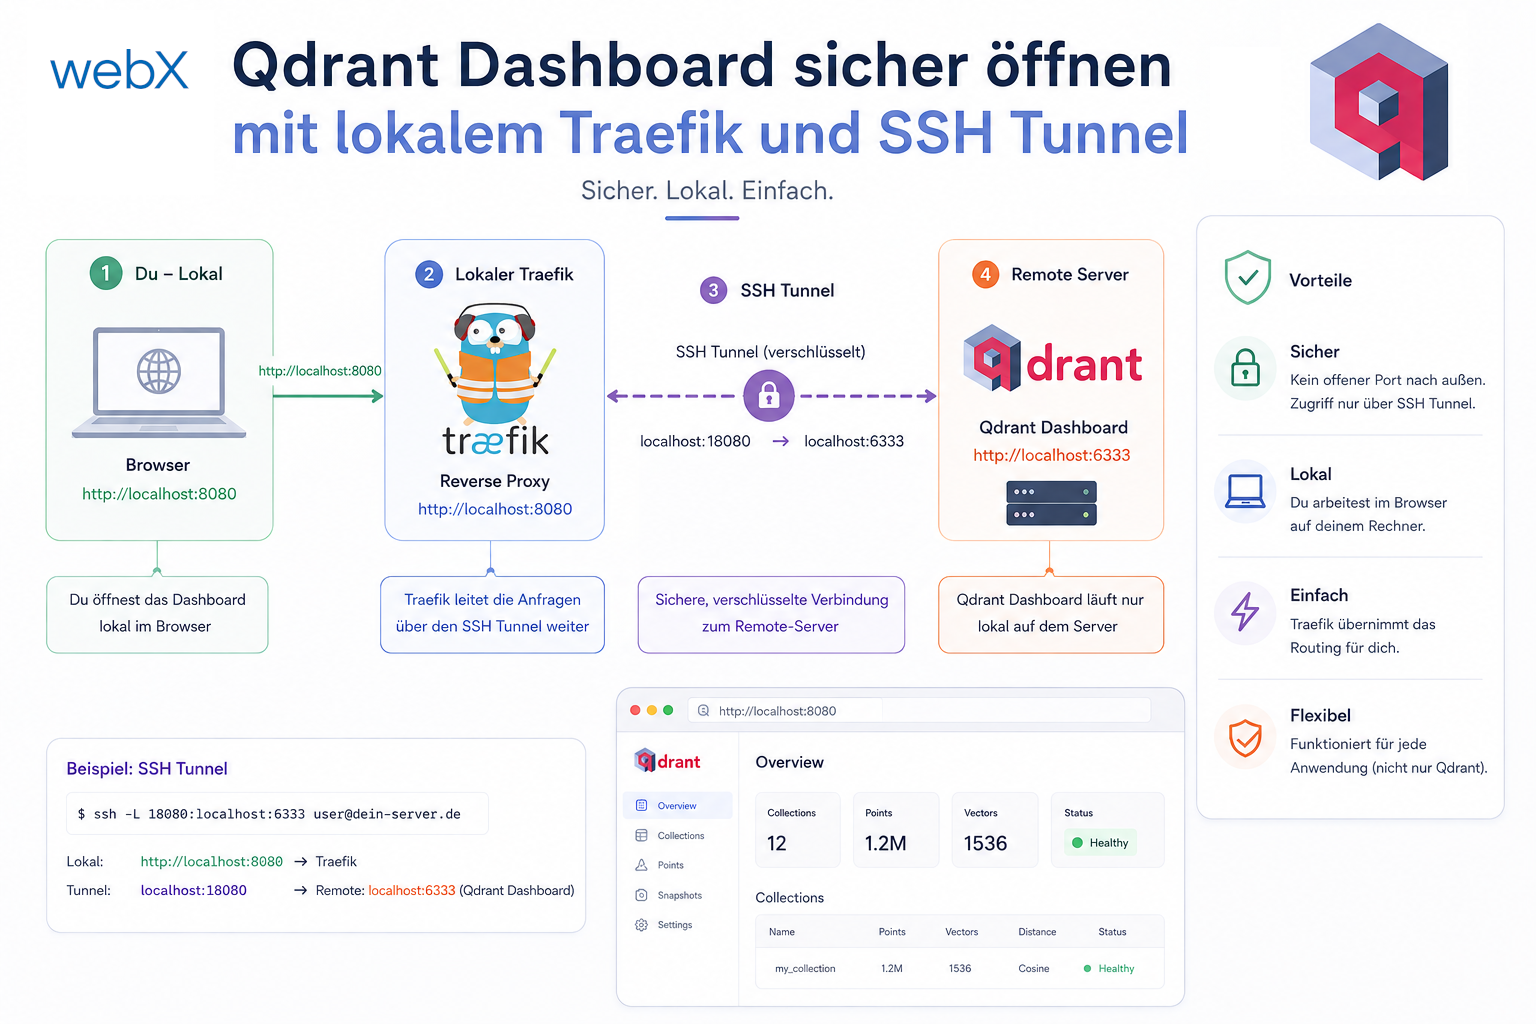
I wanted to inspect Qdrant data in the browser without making the database public. Locally I use Traefik; in production I open only an SSH tunnel and keep Qdrant internal.
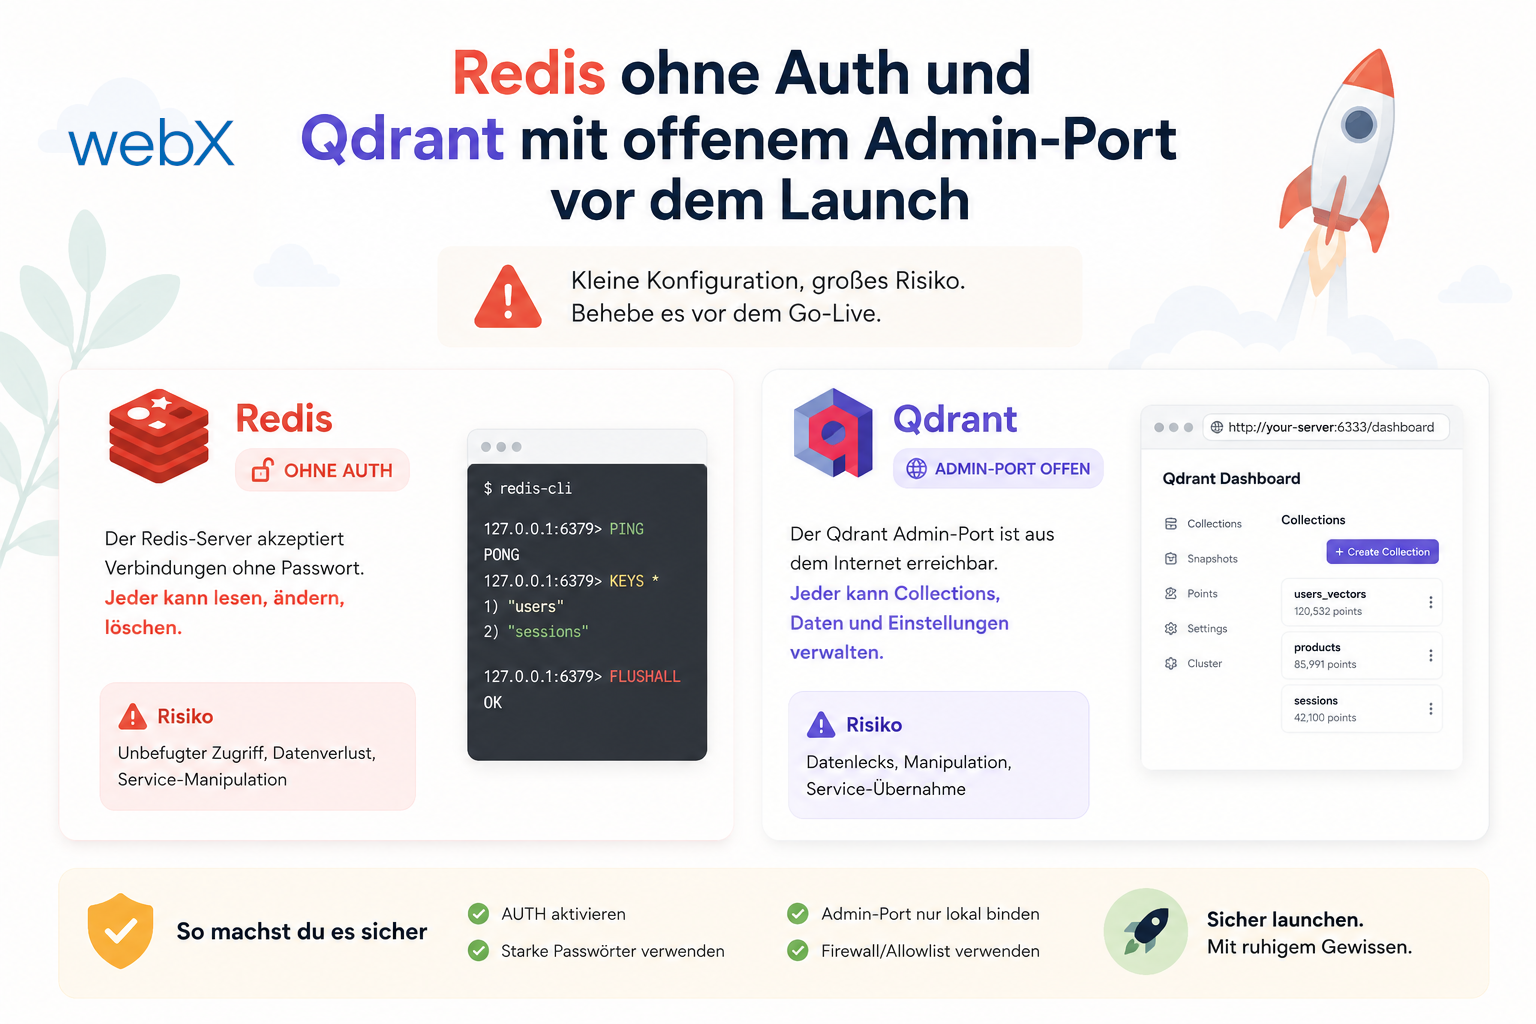
Before launch, I reviewed my architecture for more than scaling. I also examined implicit security assumptions and found two small gaps that could quickly become costly in production.
Describe your workflow. Together, we will identify the right next step.
Discuss your workflow