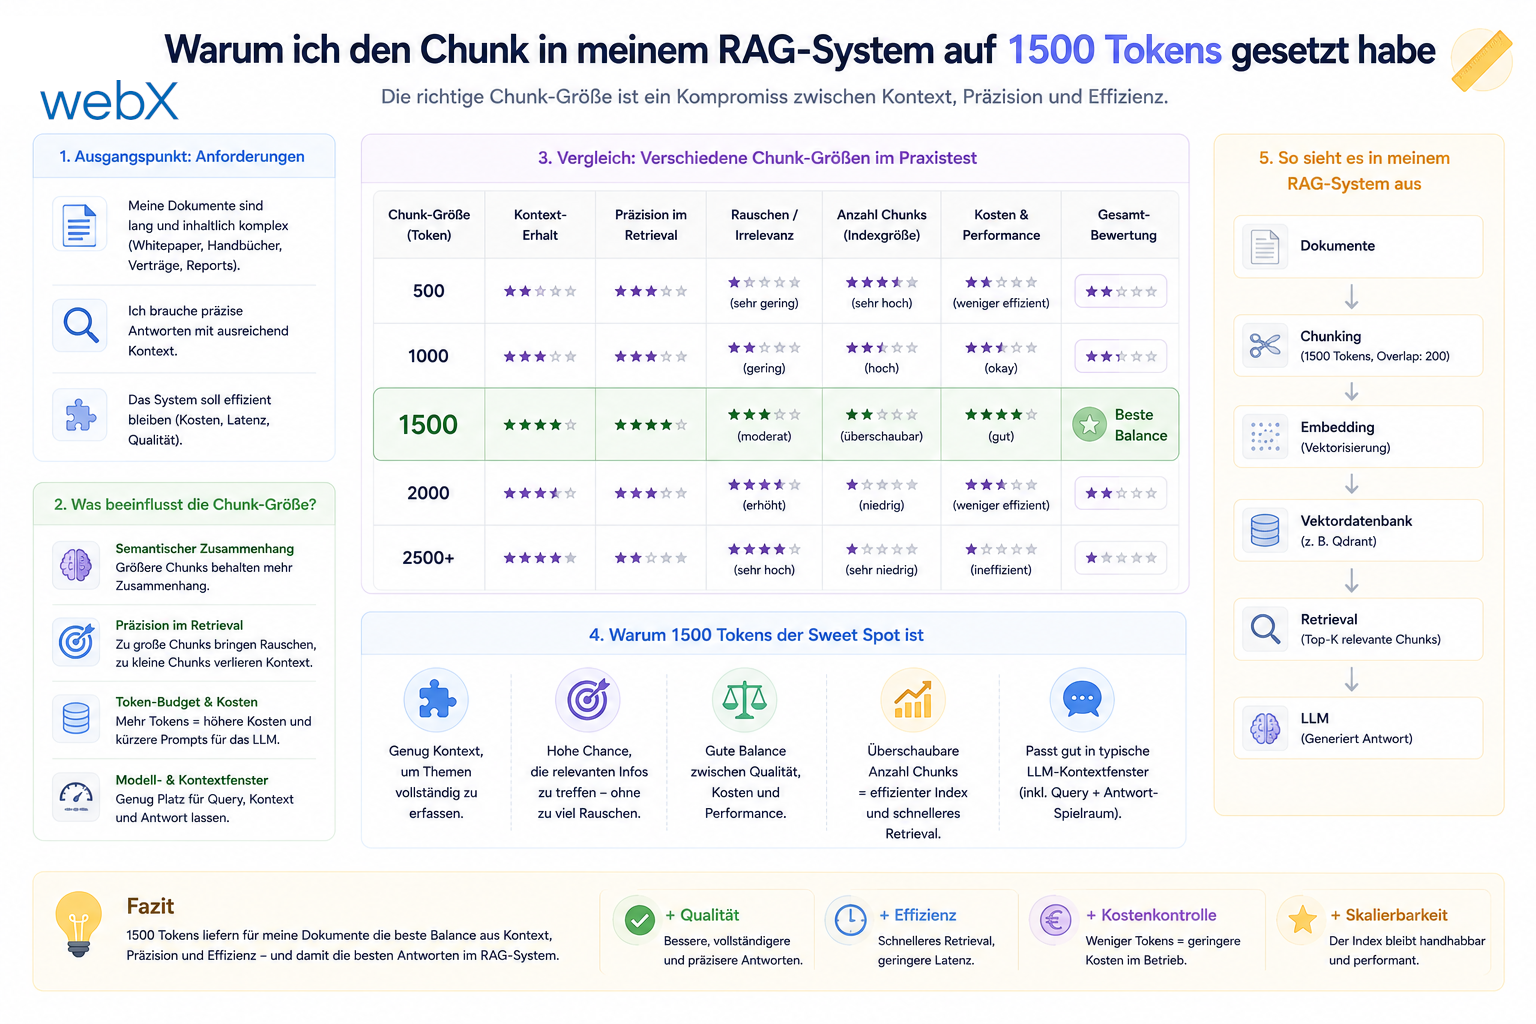
Why I set the chunk size in my RAG system to 1500 tokens
The migration to bge-m3 brought an 8192-token limit. Nevertheless, I deliberately set the chunk limit to 1500 tokens to preserve semantic focus.

The migration to bge-m3 brought an 8192-token limit. Nevertheless, I deliberately set the chunk limit to 1500 tokens to preserve semantic focus.
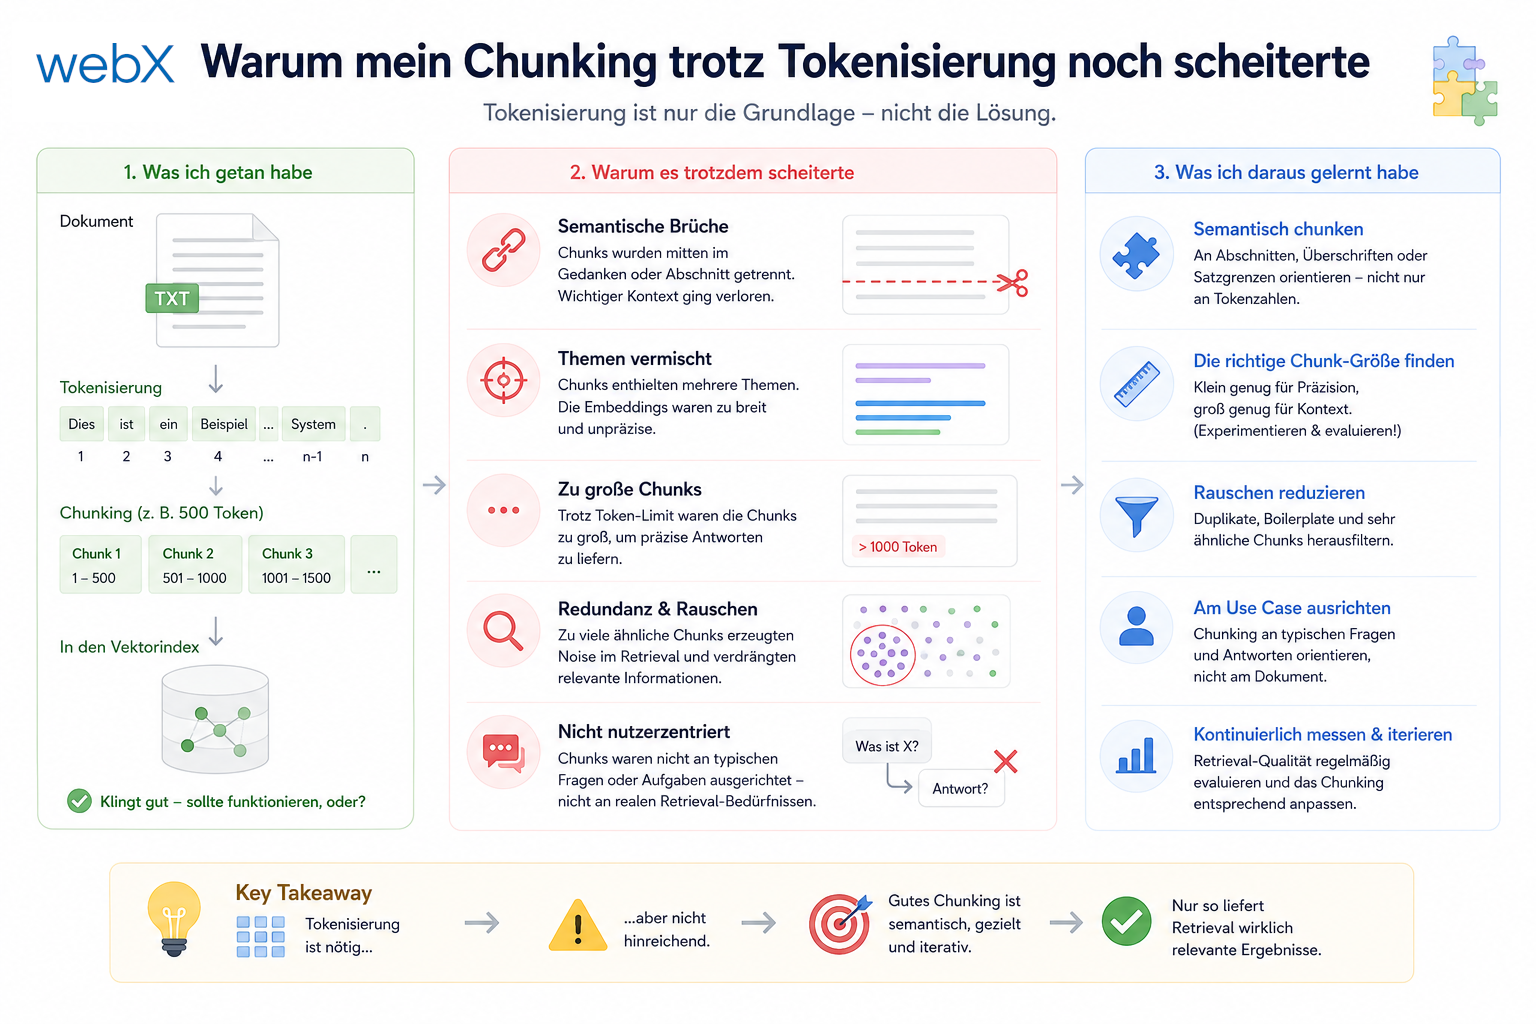
I had already implemented text splitting, but the context error kept appearing. Only when I accounted for the token budget and special tokens did the cause become clear.
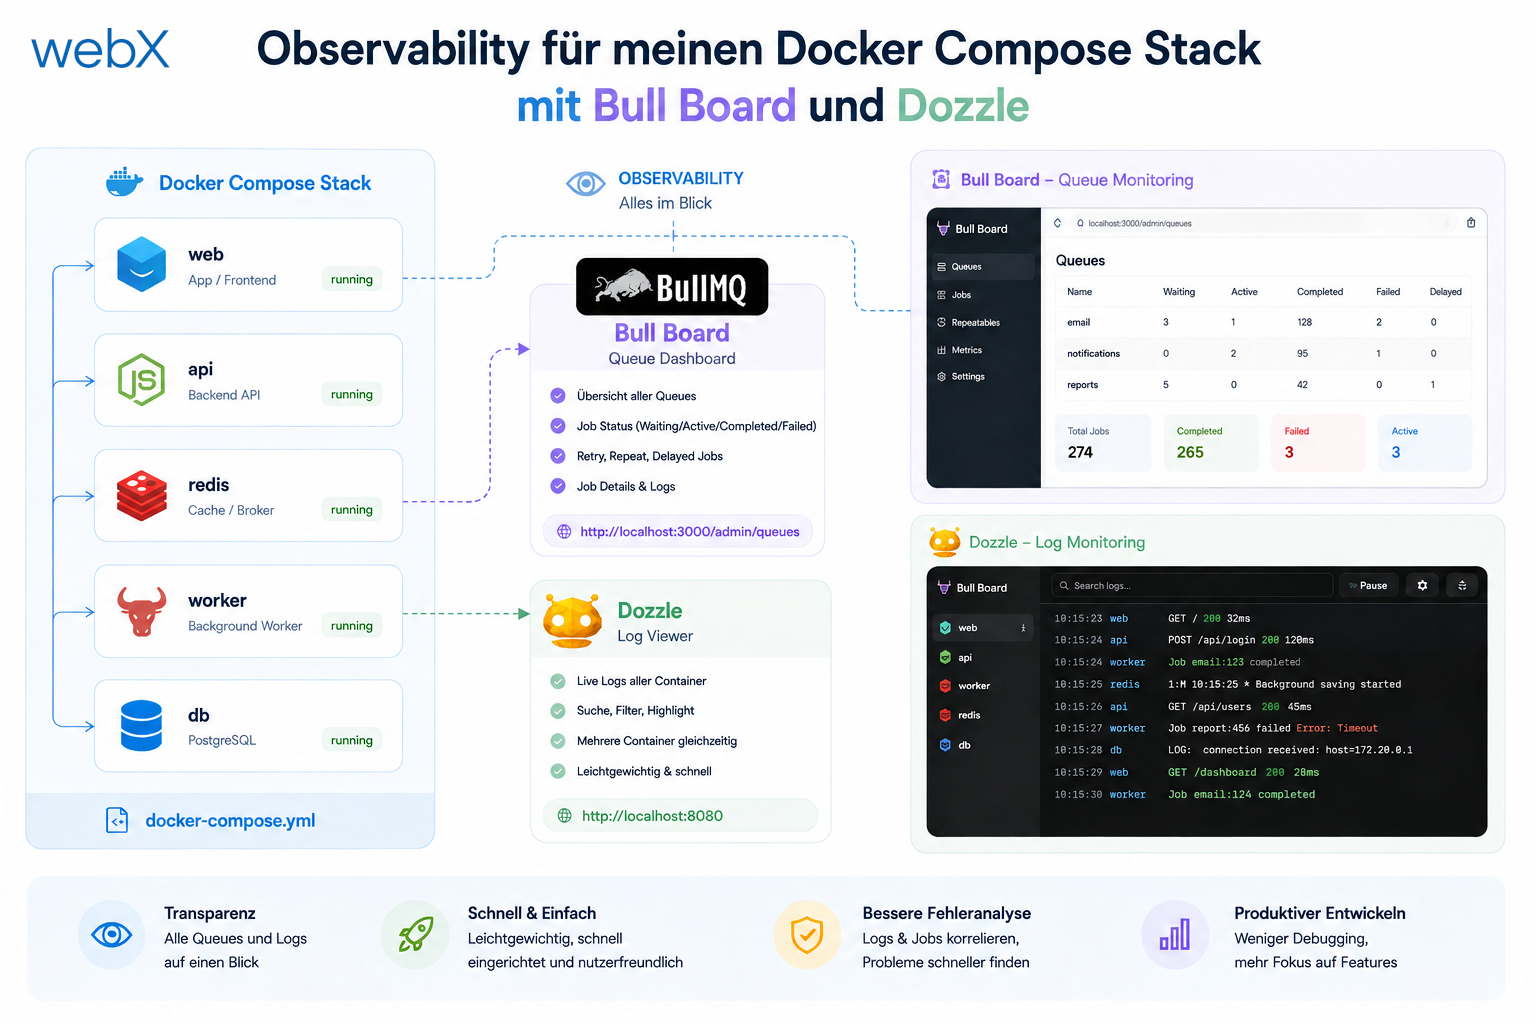
I wanted to make the path from the extension to storage visible. With Bull Board and Dozzle, I have queue status and container logs directly in the browser and can identify failures much faster.
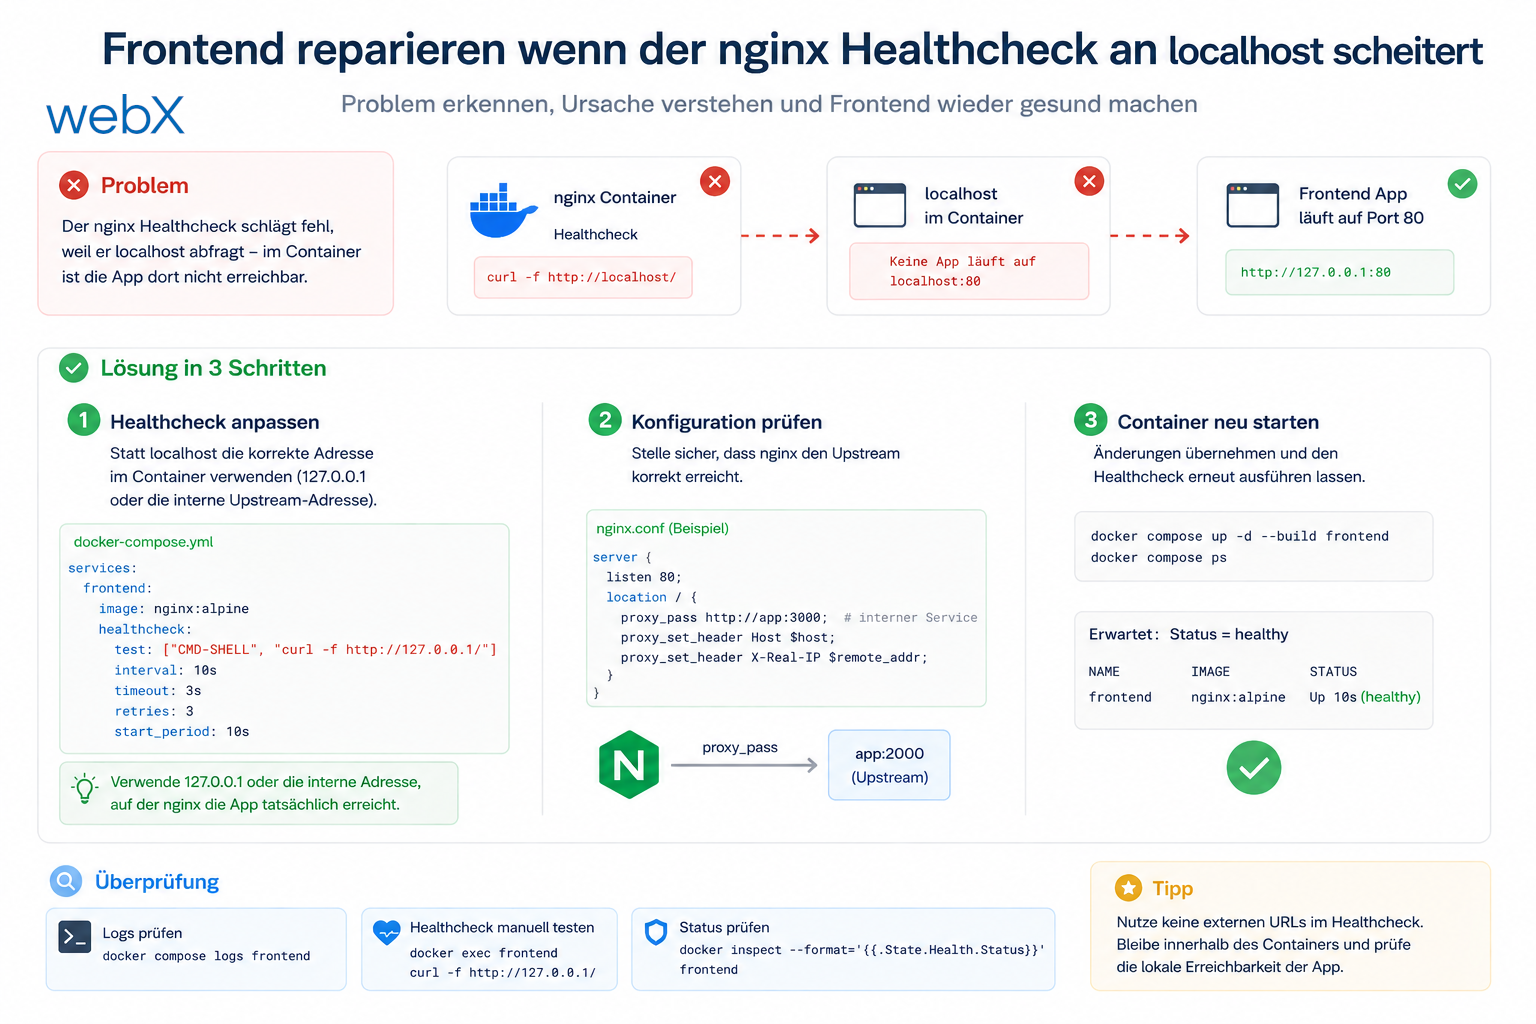
The frontend container was built and running, yet still unhealthy. The cause was a small Alpine pitfall: BusyBox Wget resolved localhost over IPv6 first, while nginx listened only on IPv4.
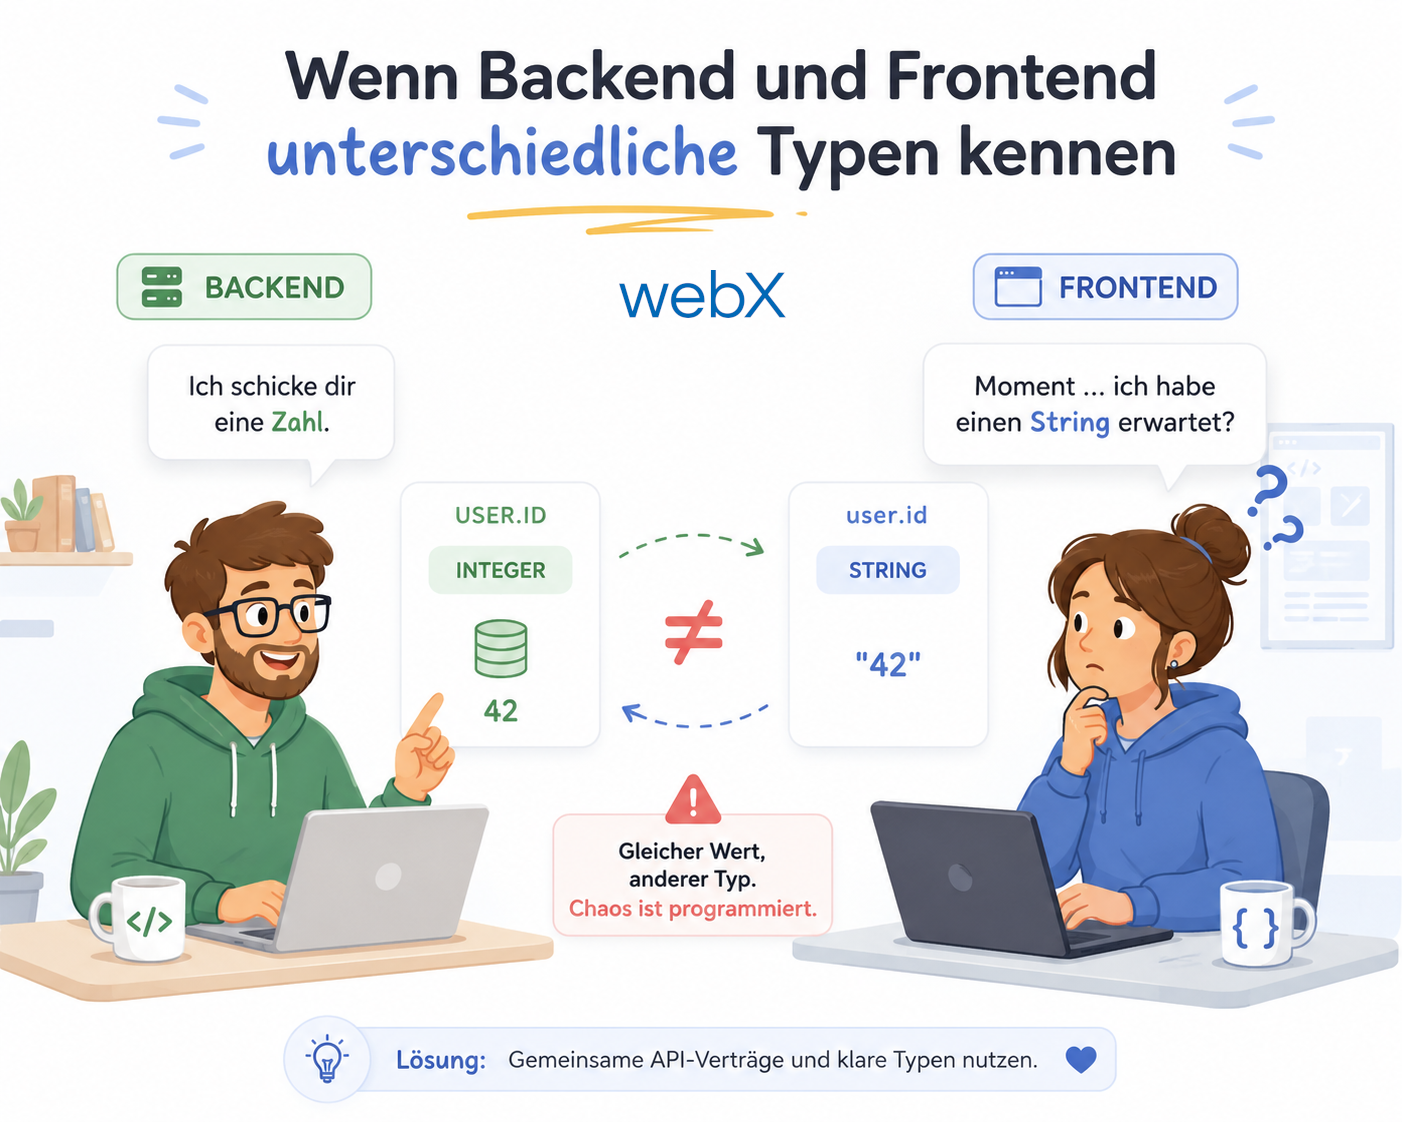
A TypeError in the browser after a backend refactoring. The cause is not a bug in the code, but an outdated frontend type that did not know the new API response shape.
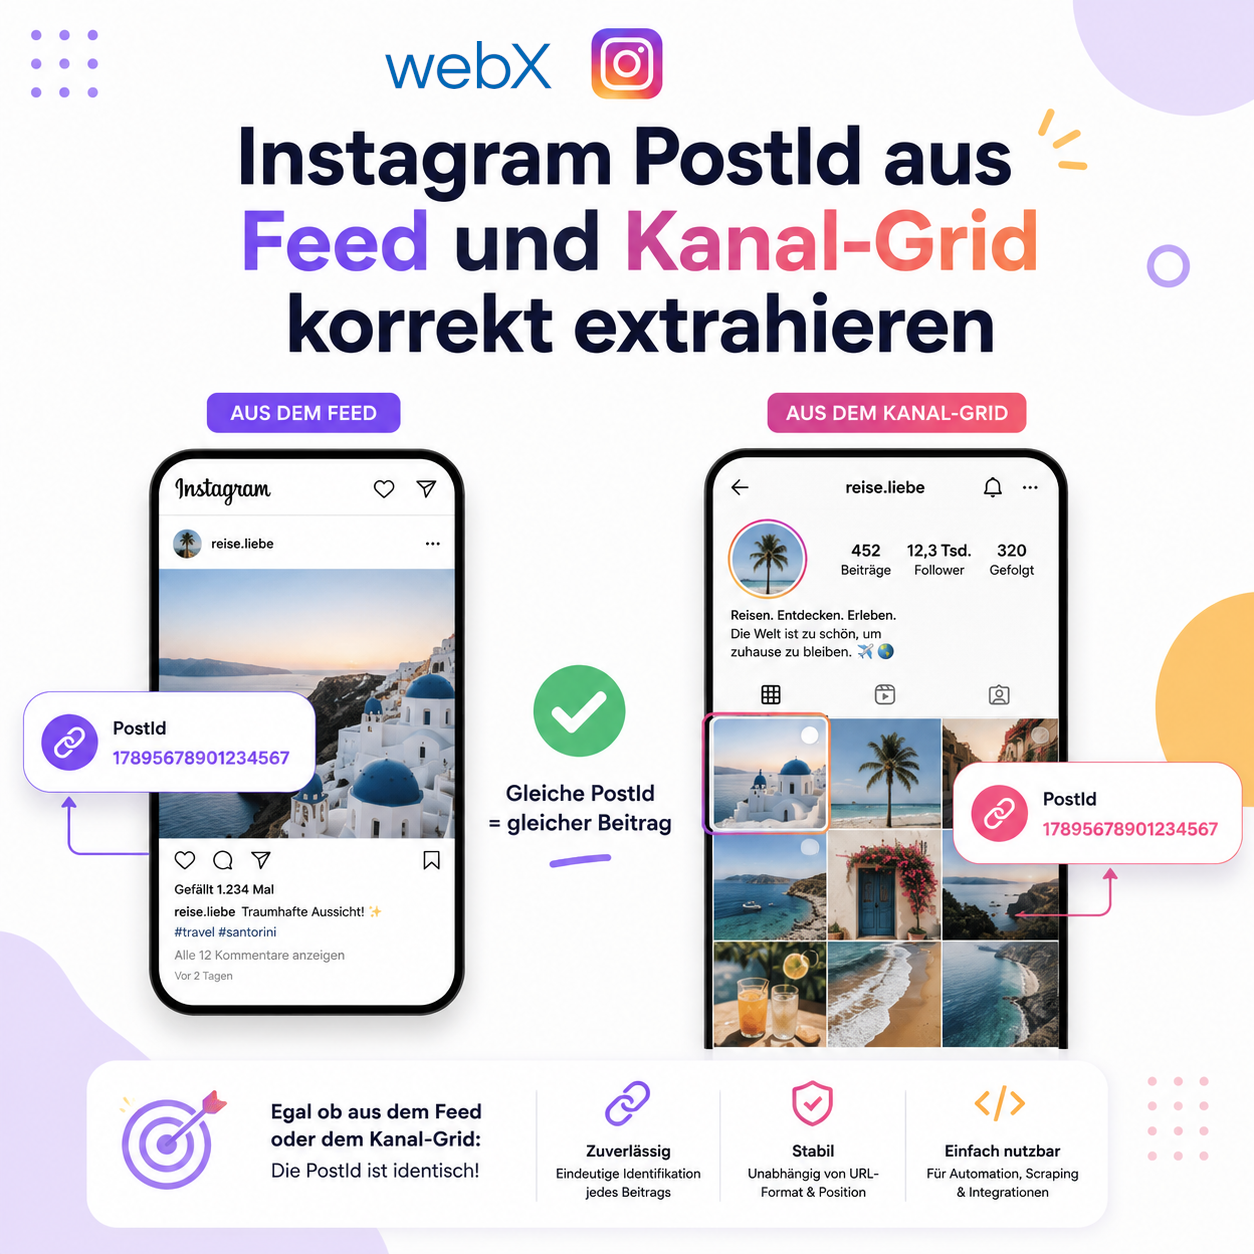
Instagram uses article tags in the feed, but not in the profile grid. Ancestor traversal fixes incorrect PostIds, while a promise map prevents duplicate backend requests.
Describe your workflow. Together, we will identify the right next step.
Discuss your workflow