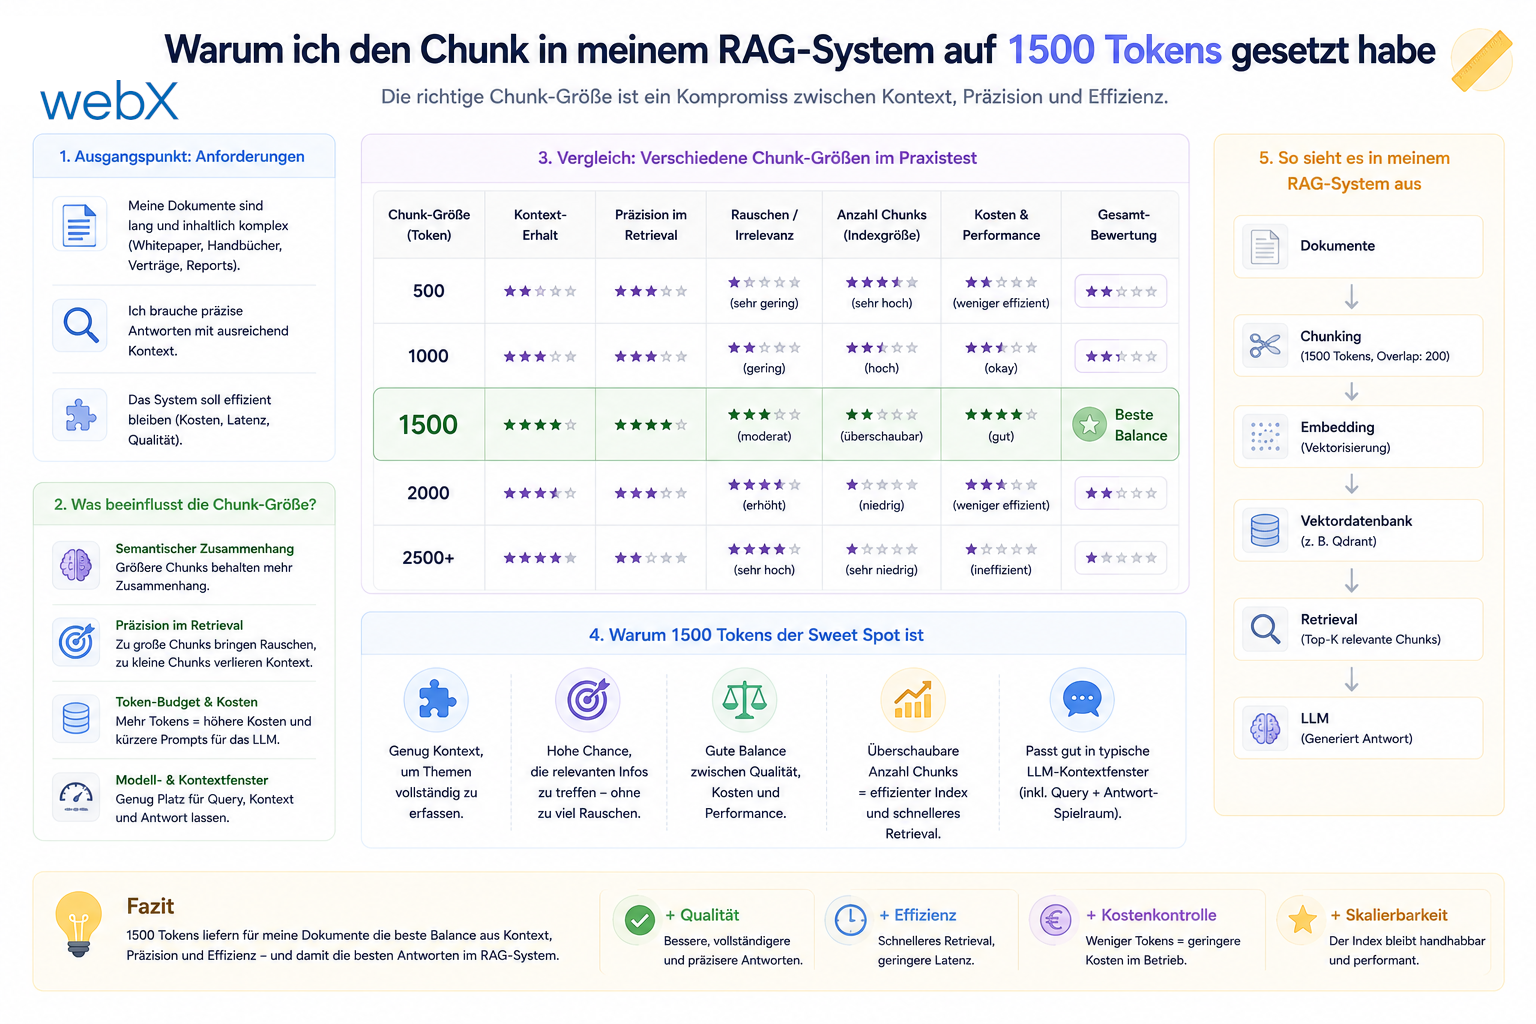
Why I set the chunk size in my RAG system to 1500 tokens
The migration to bge-m3 brought an 8192-token limit. Nevertheless, I deliberately set the chunk limit to 1500 tokens to preserve semantic focus.

The migration to bge-m3 brought an 8192-token limit. Nevertheless, I deliberately set the chunk limit to 1500 tokens to preserve semantic focus.
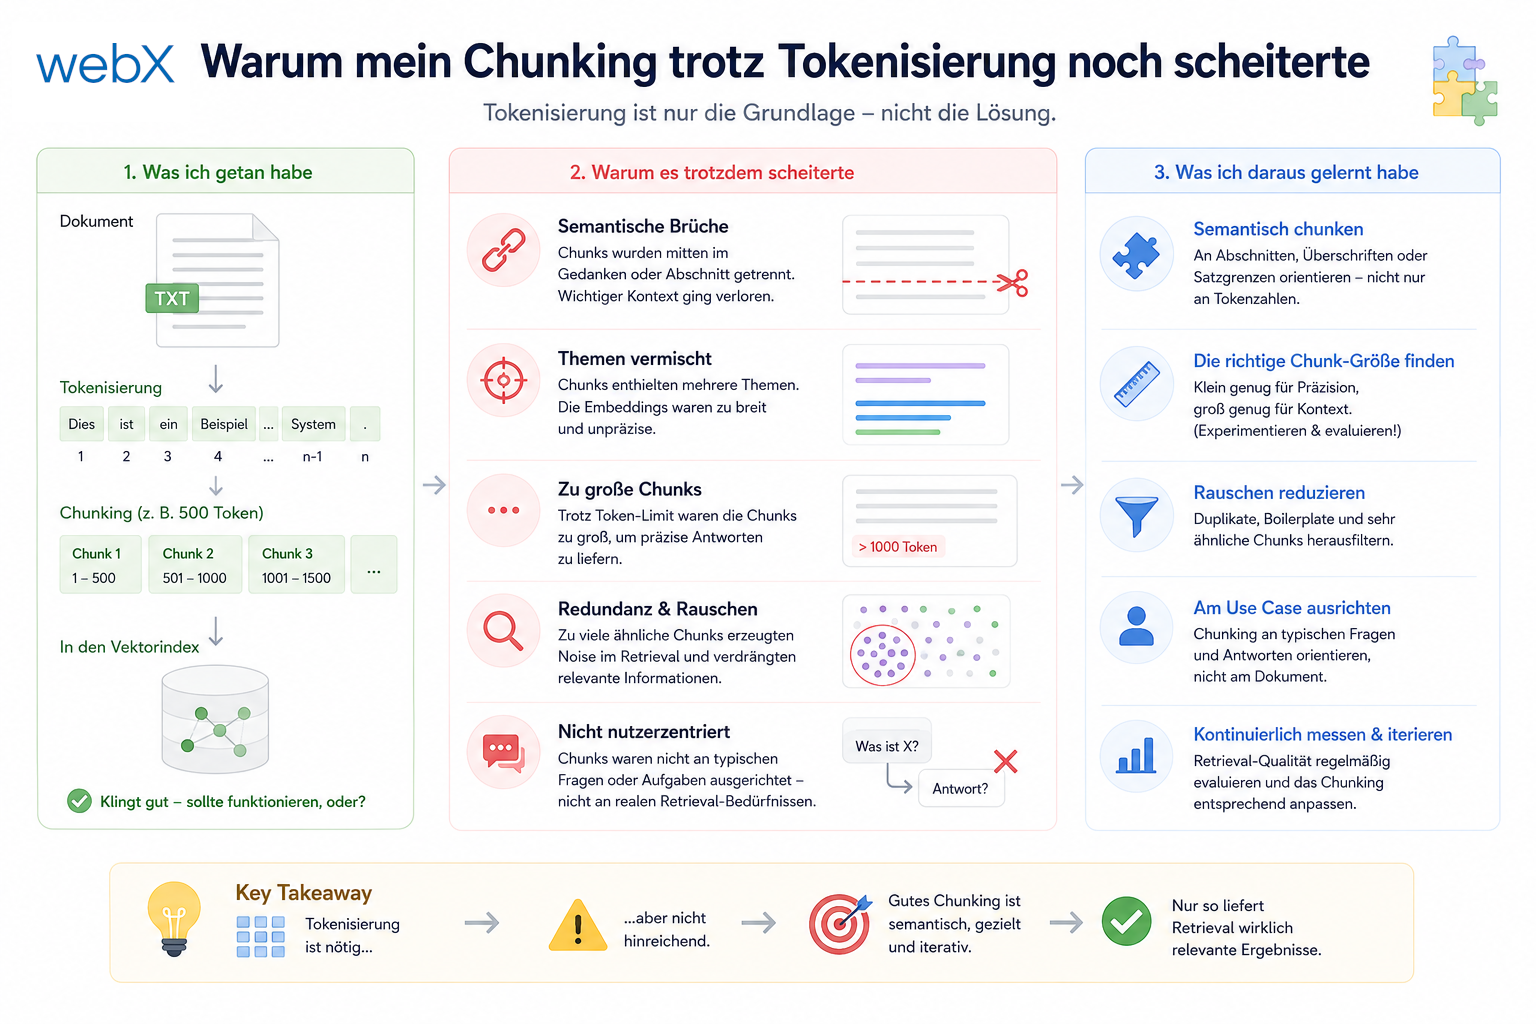
I had already implemented text splitting, but the context error kept appearing. Only when I accounted for the token budget and special tokens did the cause become clear.
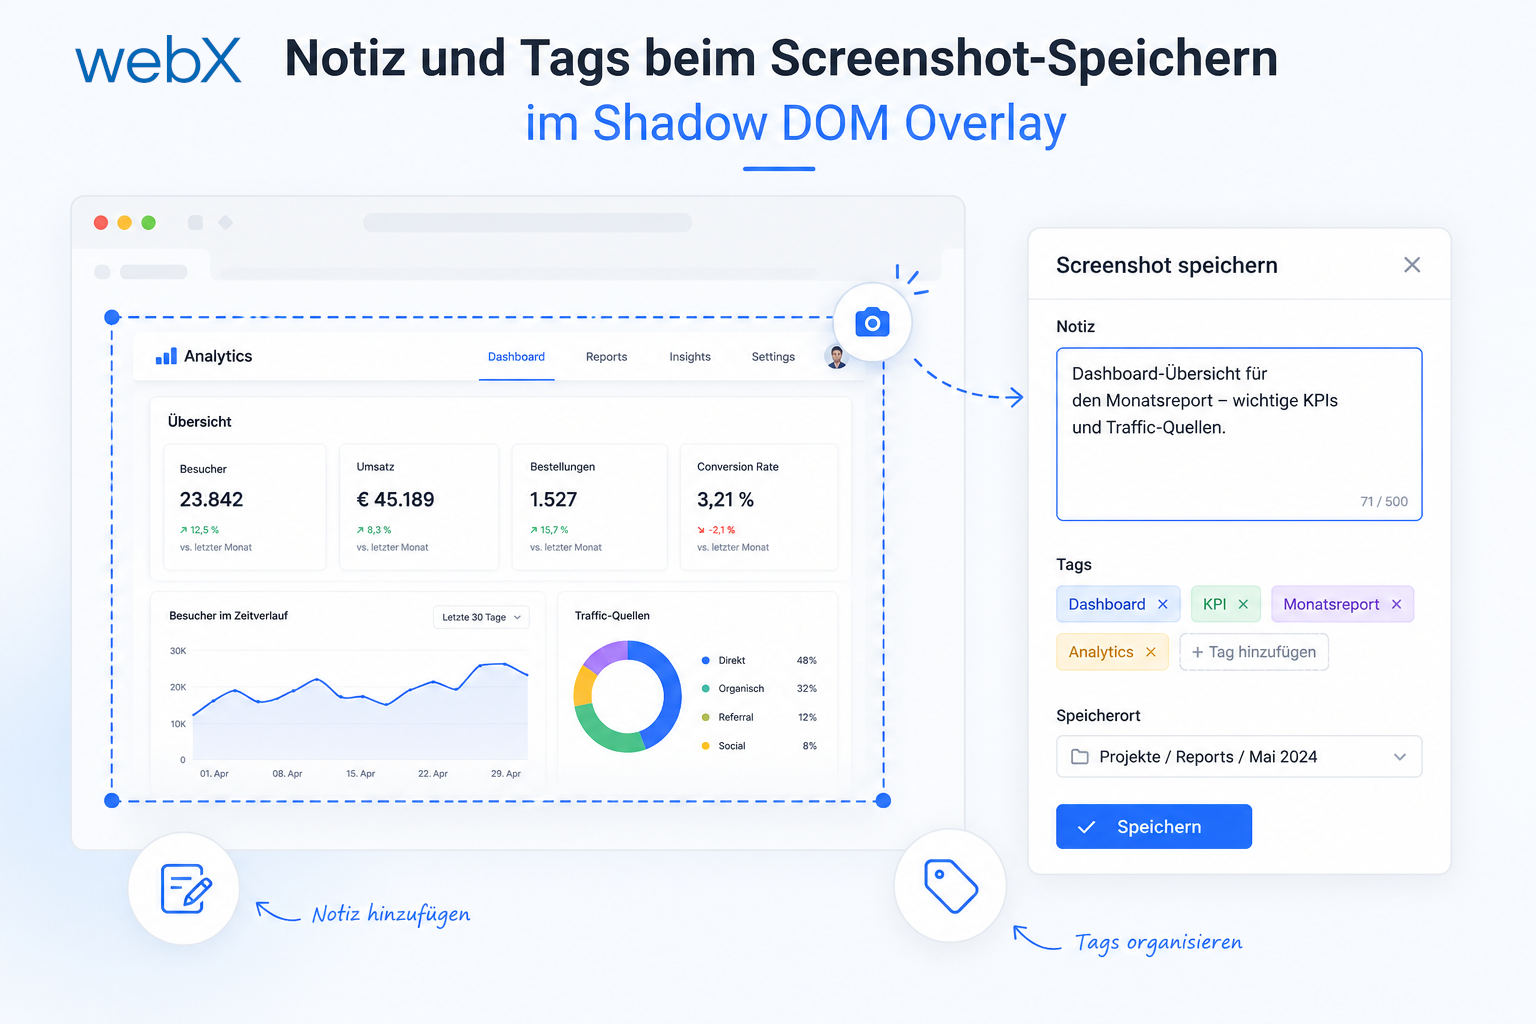
Notes and tags are entered directly in the capture overlay, persisted in Qdrant and included in the embedding. How types, Shadow DOM and a chip input make this work.
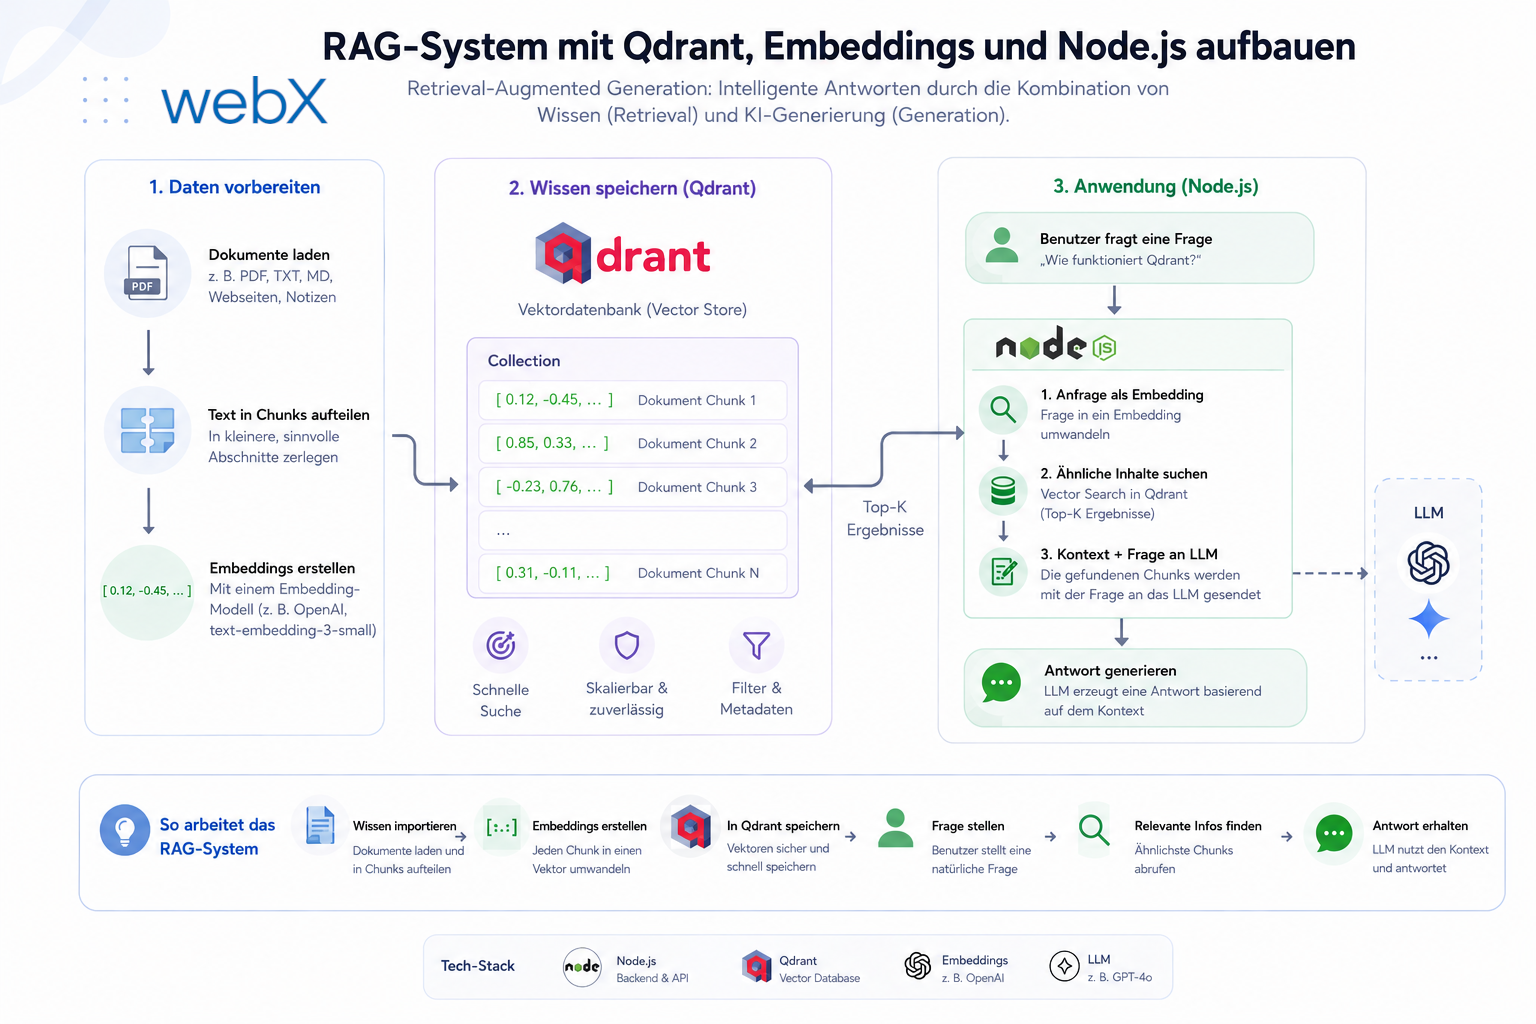
Retrieval-Augmented Generation is not theory. It is a concrete three-step architecture: embed, retrieve and generate. I show how I implemented it entirely locally with Qdrant, nomic-embed-text and llama3.2, without cloud costs.
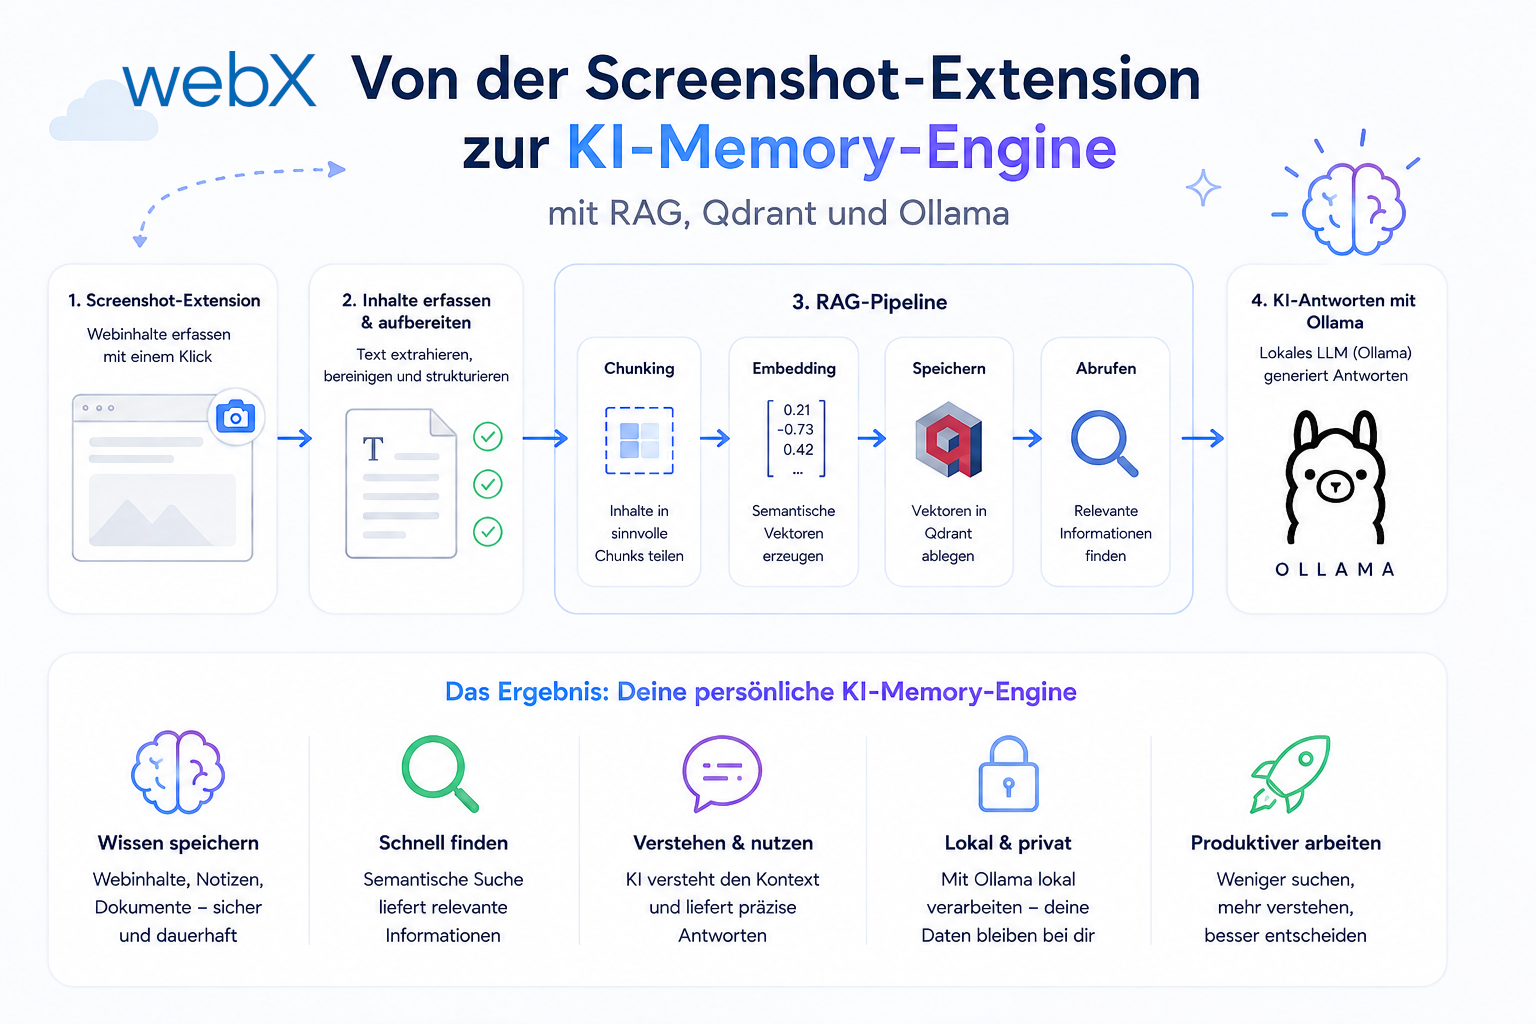
A Chrome Extension for Instagram metadata was the starting point. It grew into a complete RAG system built on Qdrant, Ollama and TypeScript that runs locally, is cloud-ready and enables semantic search across captured social media data.
Describe your workflow. Together, we will identify the right next step.
Discuss your workflow